Your AI outcomes are running out of control. Meridian keeps them governed.
The Enterprise AI Control Plane. One gateway across every agent, MCP server and model, governing quality, performance and cost - continuously.
Always-on
Quality evals against baseline
0%
of requests timed and tagged
0-0%
lower cost with Intelligent Routing or General Symbolic Reasoning
1wk
to full spend attribution
The Problem
AI has left the pilot phase.
The operating model hasn't caught up.
Cloud and Data have mature
governance frameworks. AI has
none that governs quality,
performance and cost together.
Today, managing one means
trading away another.
Cut cost, and quality erodes
Teams default to premium
models. Cheaper models save money, but quality can slip, and
without a baseline nobody
notices until a user does.
15-25%
less accurate without reasoning mode (2025
benchmark)
Raise quality, and performance degrades
Longer reasoning lifts quality but adds tokens, latency and rework. Many organizations have no latency target or clear owner for the experience.
6x
longer to restore that accuracy (2025 benchmark)
Runaway, unattributed spend
API calls, MCP servers, coding agents and AI-enabled SaaS fall outside cloud billing until the invoice arrives. Finance cannot charge back what it cannot see.
50%+
of GenAI projects overrun budgets through 2028 (Gartner)
Long tasks compound every trade-off
Agents chain many steps, and small errors compound. Most multi-step tasks hit an error, and retries add delay and spend.
>30%
Likelihood of multi-step tasks failing
The Solution
The Enterprise AI Control Plane
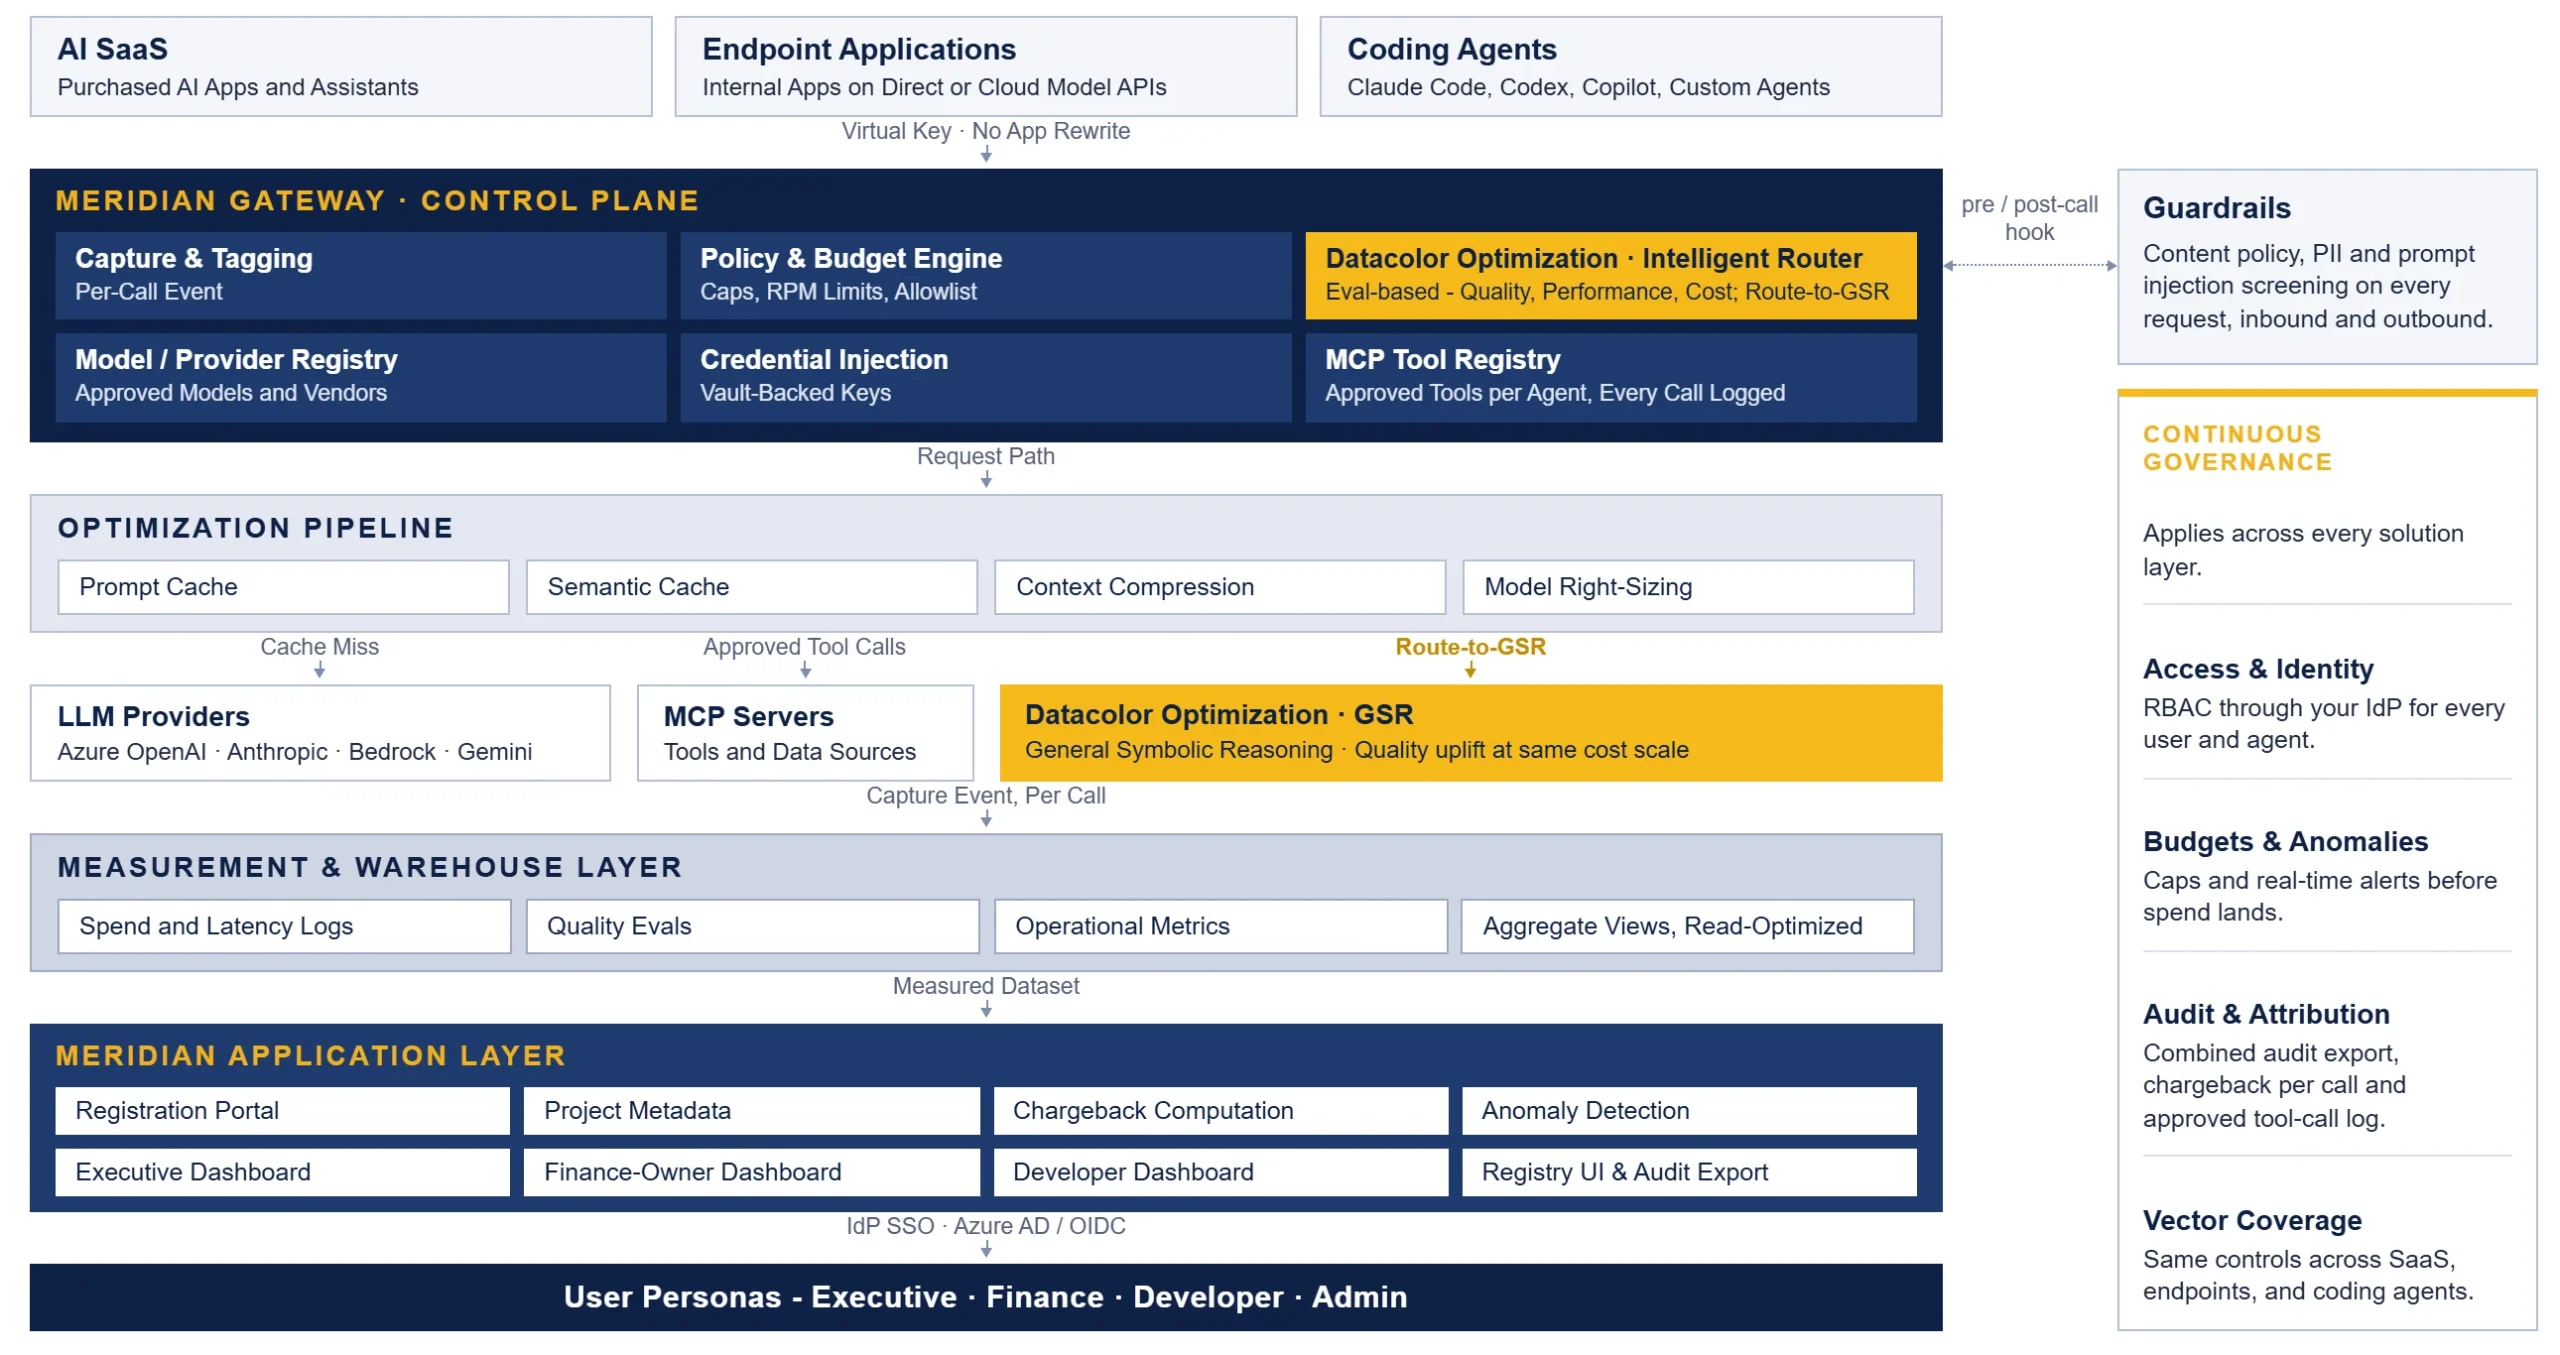
Meridian governs quality, performance and cost together through a single gateway, without changing how your teams build. It instruments every request, measures all three, makes spend visible and optimizes continuously.
Instrument
Every request captured and tagged, automatically.
Measure
Quality, performance and cost, down to a single request.
Visualize
One dataset, a dashboard per audience.
Optimize
Six levers, applied only where they pay off.
Gateway
One endpoint, every provider
One endpoint to OpenAI, Anthropic, Google, Azure, AWS Bedrock and 100+ others, scoped to an approved-model allowlist. Virtual keys with spend caps and auto-revoke. MCP and A2A support built in.
Optimization
Six levers, two that go further.
Model right-sizing, prompt caching, semantic caching and context compression are built in. Datacolor Intelligent Routing evaluates quality before a switch is trusted. Datacolor General Symbolic Reasoning (GSR) plans complex, long-horizon tasks before the model runs.
Governance
Governance, enforced on every request
Configurable guardrails screen every request for PII and prompt injection, then block or mask it before it reaches a provider. Policies set which model families each project, team or role can use, with budgets and spend caps enforced before spend happens. Every decision is logged for audit, with SIEM-ready exports.
Integration
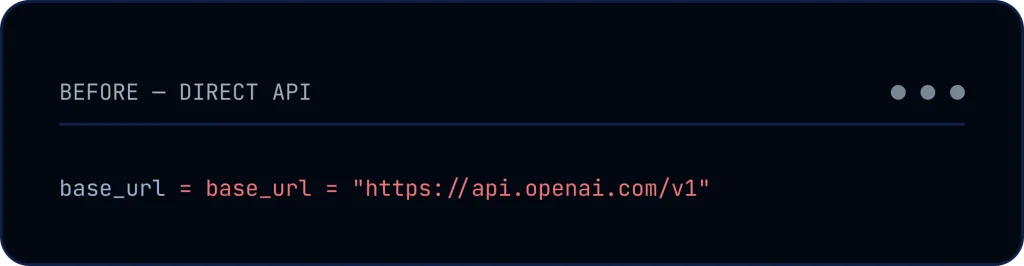
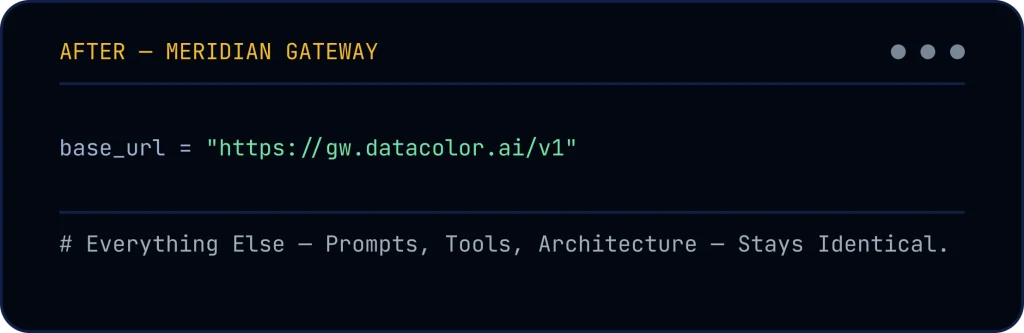
Change the endpoint.
Nothing else.
Most integrations complete in under 4 hours. No agent
re-architecture. No prompt re-work. No new infrastructure.
Kickoff and baseline
Datacolor engineers capture your current spend baseline within 24 hours of kickoff. No agent code changes, no security review required.
Instrument your estate
The gateway is configured for your model × cloud combinations. Agent metadata model maps costs to departments and accounting codes.
Activate optimization levers
Routing, Context Compression and Semantic Caching activate first for immediate impact. Eval-based Routing and GSR activate on your highest-spend agentic workloads.
Deliver a defensible ROI number
A measured before-and-after comparison on your real workloads. Finance-ready chargeback from day one.
Business Outcomes
What you actually get
Eight outcomes that balance quality, performance and cost. Each attributable. Each measurable within your first 30 days.
Full visibility
Every request attributed to its team, project, user, model and environment, with quality, latency and cost scored together.
Quality you can prove
Always-on evals against your baseline show whether a cheaper or faster model holds your quality bar, before and after every change.
Performance you can plan around
Every request is timed and tagged, so latency is tracked by model and workload, and speed against cost becomes a choice you make.
Lower cost, same quality bar
Datacolor Intelligent Routing or Datacolor General Symbolic Reasoning lowers cost 30% to 50%, checked against your quality baseline.
Complex work done right
Datacolor General Symbolic Reasoning keeps long-horizon agent tasks on plan, with an execution trace your team can review.
Predictable spend
Budgets, hard-stop limits and real-time alerts prevent runaway spend. Finance gets reliable monthly forecasts.
Responsible agent scaling
Roll out coding agents and custom agents across hundreds of engineers with budgets, guardrails and model policies from day one.
Governed by design
Guardrails for PII and prompt injection, model-family allowlists by project and role, and an audit trail for security reviews.
Competitive Position
Why Meridian is different
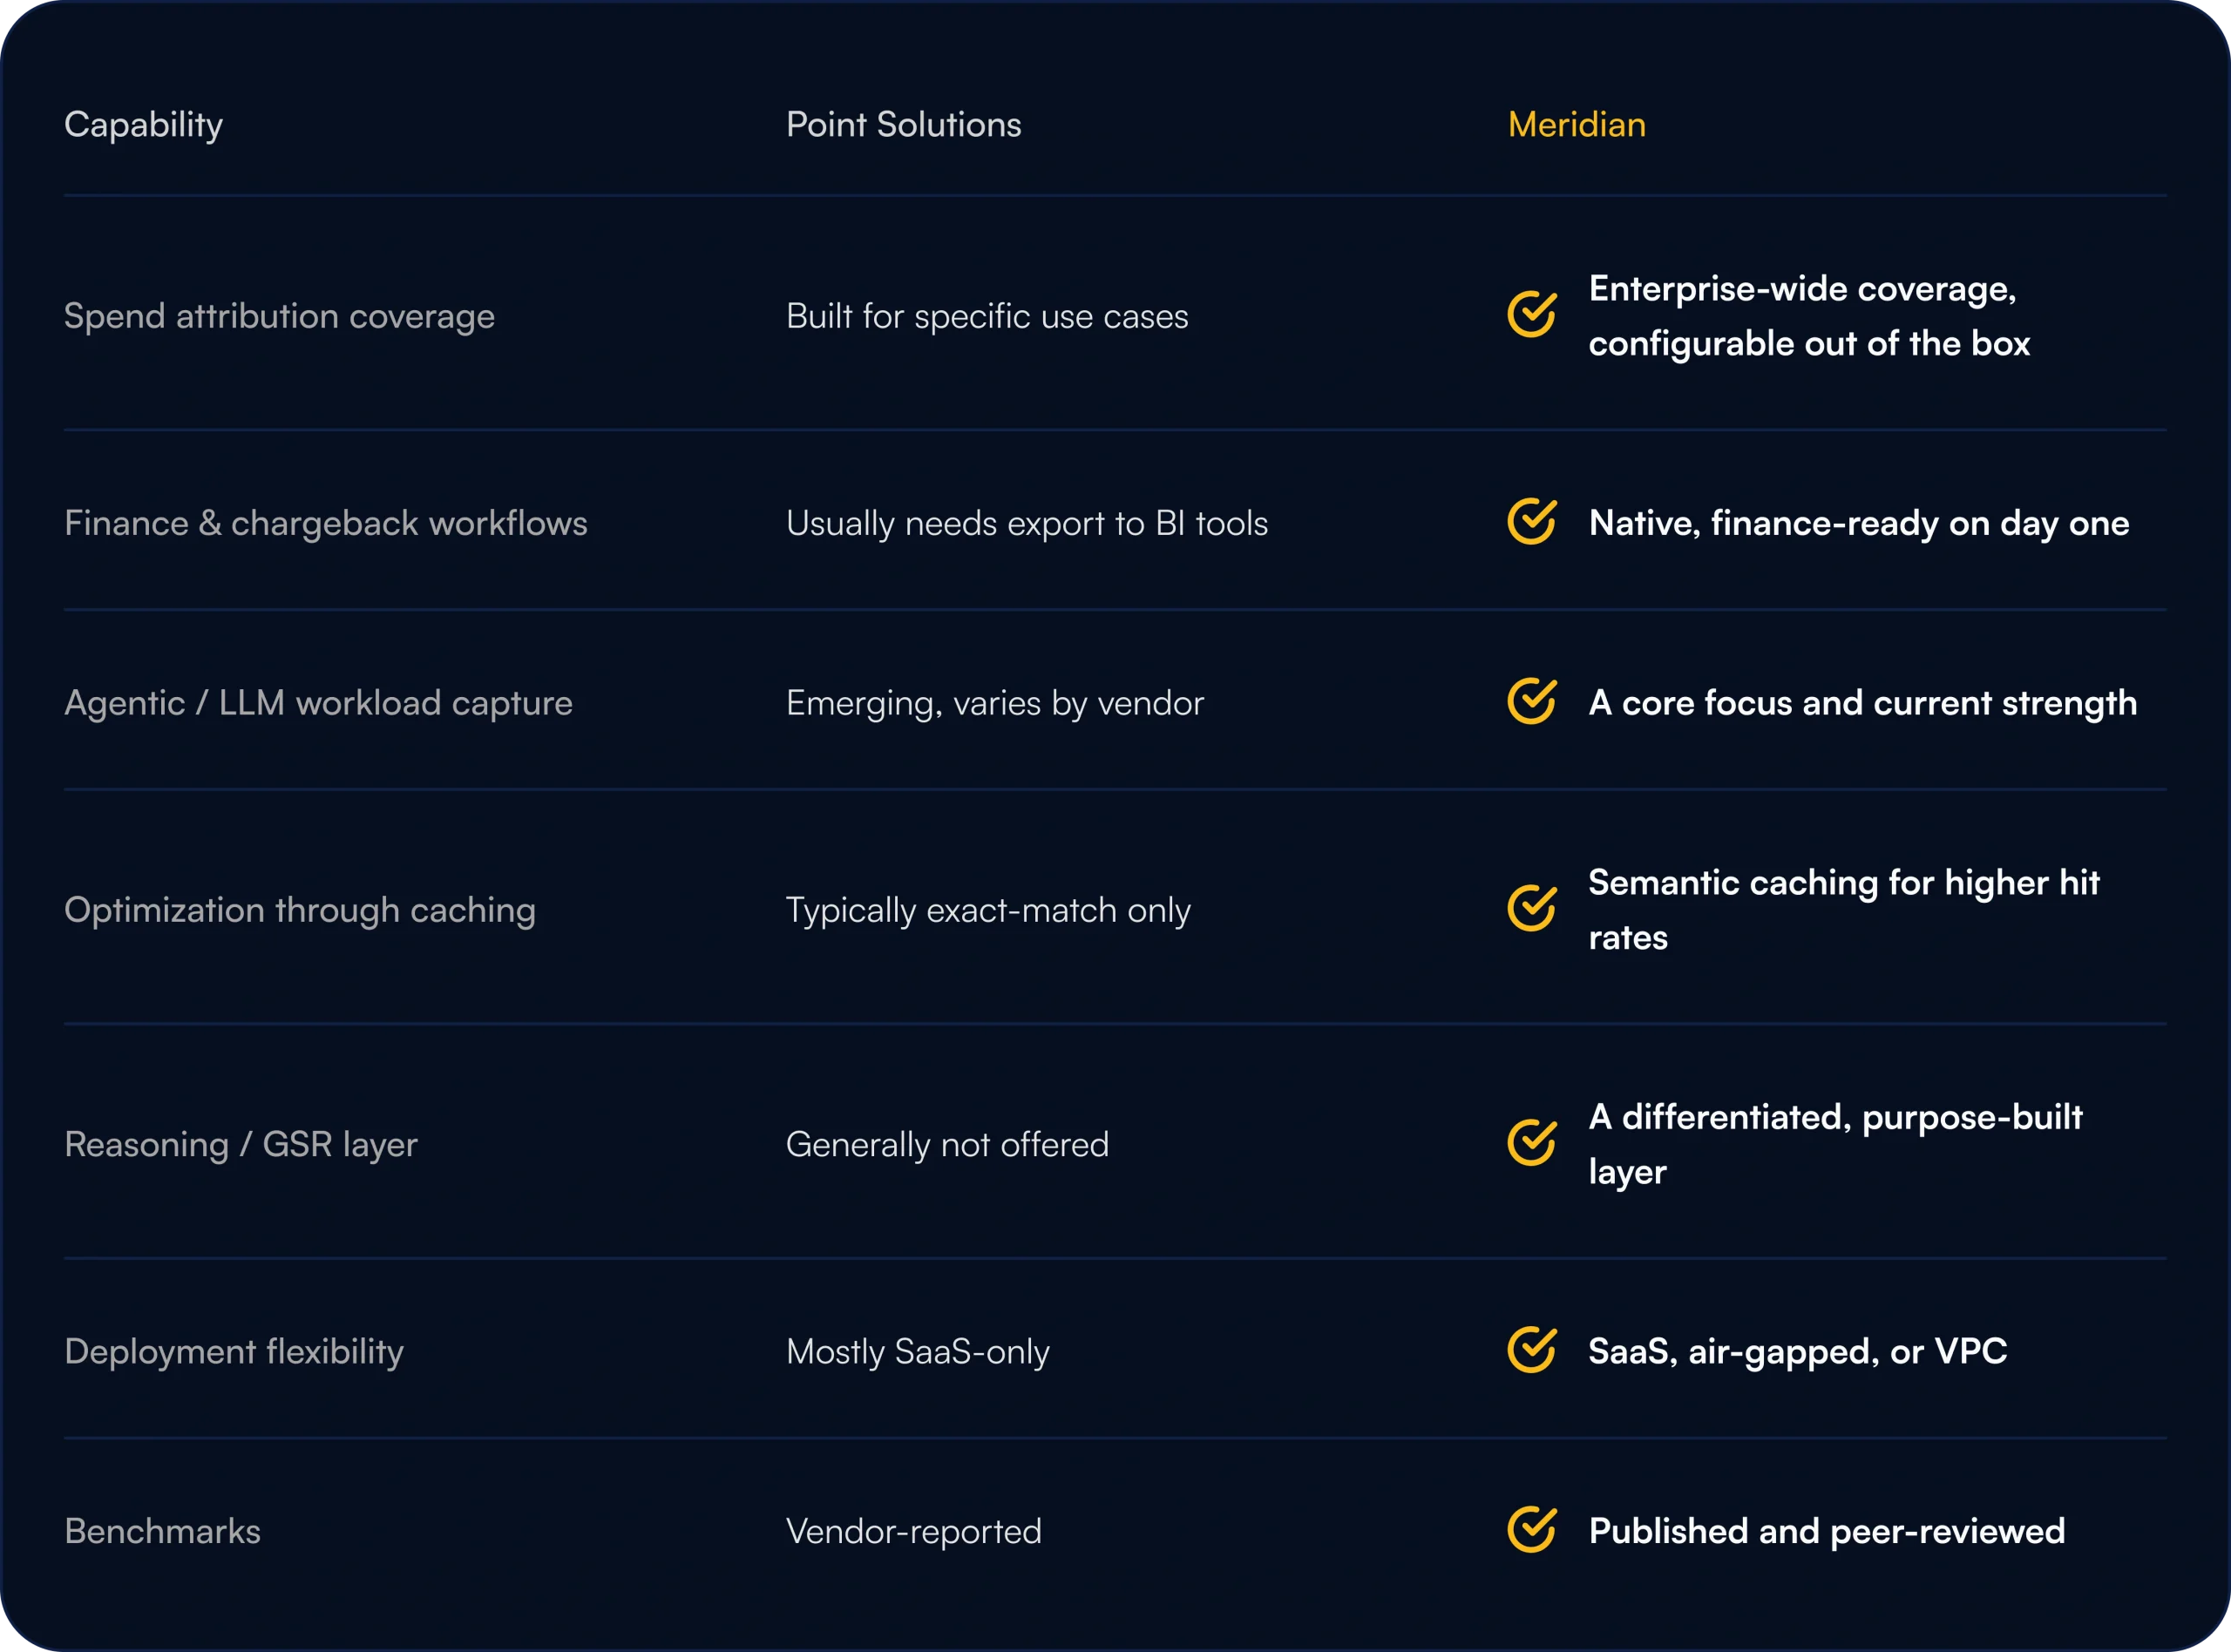
Observability platforms tell you what happened after it happened. BI dashboards describe the spend without changing it. Cloud FinOps tools weren't built to understand tokens, model tiers or agents. Meridian is the control point - and the only peer-reviewed reasoning layer on the market.
Built for specific use cases
Enterprise-wide, 100% coverage
Continuous quality measurement
Not tracked systematically
Per call, against your evals
Continuous eval-based routing
Static rule sets, rarely revisited
Self-relearning, per task
A differentiated, purpose-built layer
Typically exact-match only
Semantic, higher hit rates
Usually needs export to BI tools
Native, finance-ready on day one
Published and peer-reviewed
Six optimization levers together, an industry-first
Leverage Model right-sizing, Prompt Caching, Semantic Caching, and Context Compression almost across all use-cases. Bundled with Continuous eval-based Intelligent Routing and Datacolor GSR for curated optimization across priority use-cases.
Visibility first, then defensible optimization
Meridian establishes a measured baseline before activating any optimization lever. Every savings claim is backed by a before-and-after comparison on your real workloads - not vendor projections.
One thin layer. Zero re-architecture.
Agent architecture, prompts, tool definitions, and downstream consumers remain completely unchanged. The entire estate - direct APIs, cloud-hosted models, coding agents - captured through a single, provider-agnostic gateway hop.
Built for Finance, not just Engineering
The agent metadata model produces chargeback reports Finance can actually post. AI cost becomes a first-class financial metric - not a quarterly retrospective where the number is already locked.
The Business Case
Measured on your workloads
The business case is built on your own workloads, not industry averages. Quality, performance and cost are measured together, so every saving is checked against your quality bar.
30-50%
Lower cost with either lever
With Datacolor Intelligent Routing or Datacolor General Symbolic Reasoning, against direct model use on your own production workloads.
Always-on
Quality evals
Every optimization is scored against your quality baseline, so savings never come from quietly lowering the bar.
100%
Of requests timed and tagged
Latency, tokens and cost captured for every request, by project, team and model. No agent code changes.
Nearly 70%
Lower cost per successful outcome
With all six levers combined: four built in, plus Datacolor Intelligent Routing and Datacolor General Symbolic Reasoning.
2 weeks
Proof of value
Run Meridian on your workloads and see measured quality, performance and cost before you commit.
Advisory Board
AI industry leaders and academic experts
Meridian's product direction is shaped by practitioners who have built and operated AI infrastructure at scale - from enterprise software leaders to the researchers who published the benchmarks it runs on.
Priya Reddy
Founder & CEO, AI & Data Strategy & Innovation
Priya Reddy Consulting
"Turning startup chaos into enterprise credibility requires the kind of AI cost visibility that Meridian delivers - the boardroom finally has numbers it can trust."
Babar Bhatti
Chief AI Officer
Prism
"Building AI-augmented organizations means making every LLM investment accountable. Meridian is the control layer that makes that possible at scale."
Colin Hare, Ed.D.
EVP & Global Practice Lead: Analytics & Growth Consulting
Circana
"Enterprise AI governance starts with knowing where every dollar goes. Meridian gives analytics and consulting leaders the spend attribution they've been missing."
Arjun Srinivasan
SVP - AI & Data Science
ShipStation Global
"Technology strategy means nothing without financial discipline. Meridian brings FinOps rigor to the AI estate that every data and AI executive needs right now."
Dr. Ashim Bose
Professor in Naveen Jindal School of Management, UT Dallas
Former SVP & GM Data, Analytics, AI in RealPage, Inc
"Becoming AI-first demands more than adopting models - it demands operational discipline over cost, quality, and governance. Meridian is the infrastructure that enables that discipline."
Customer Outcomes
What early adopters are seeing
35% quality gain
on multi-step document processing
The quality improvement on multi-step document processing, without touching our agent code, was unexpected. $2.1M of annualized AI spend is now under governance alongside it.
Head of AI COE
PE-backed Healthcare Group
$190K
in savings per quarter, across multiple workload types
We started with a single workload. Once it matched frontier-model quality at roughly a third of the cost, we expanded to features, PRs, functions and agent runs, all on the same optimization layer.
VP of Engineering
Leading Mortgage Industry Firm
6 mo → 2 wks
to finance-ready chargeback
Finance had asked for AI cost chargeback for six months. Meridian gave them a report they could post against budget codes.
Chief Data Officer
Mid-Market Financial Services
How to Engage
Prove it on the workload that matters most.
Start with a 2-week POC on your highest-value workload. Measure twice-baseline, then with Meridian-holding quality constant while cost moves, for a defensible number.
Week 1
Instrument and baseline
The gateway is configured for your top model × cloud combinations. Attribution is live by end of week one.
Week 2
Activate and measure
Routing, caching and GSR activate on your highest-spend workloads, then re-run for a defensible delta.
Beyond Week 2
Production and governance
Deployment in your VPC or on-prem, air-gapped capable. Always-on quality, anomaly and budget governance.
Start your 2-week POC
→ Baseline results within 24 hours of kickoff
No commitment. Baseline results within 24 hrs. Your data is never shared.
Prefer to write directly? partner@datacolor.ai